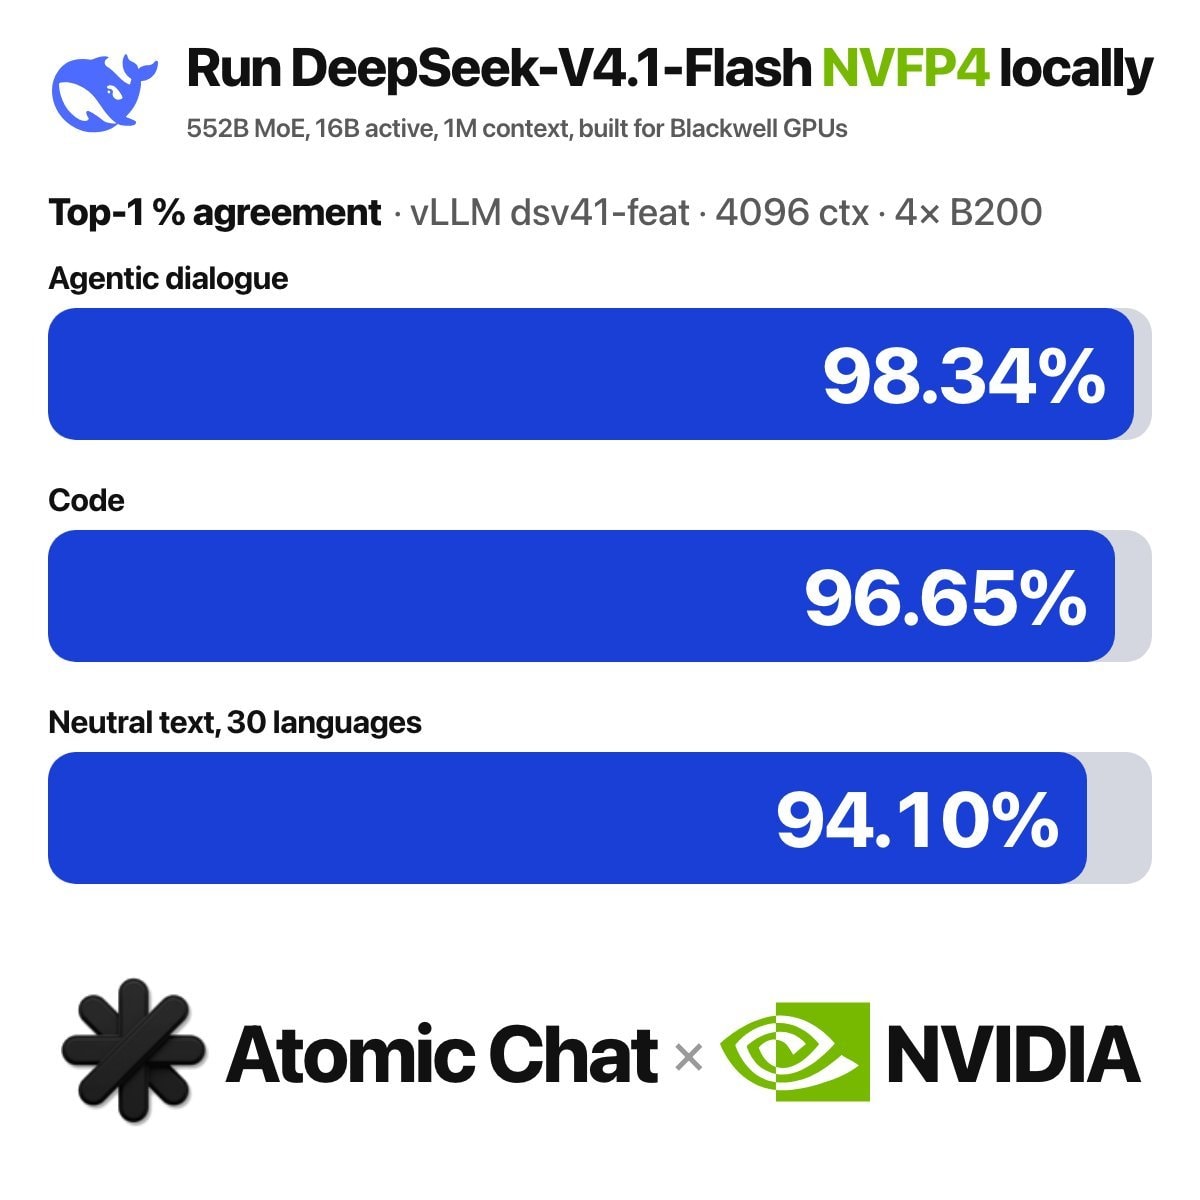
@nate_512LOCAL INFERENCE JUST GOT A MASSIVE UPGRADE atomic_chat_hq did it again 💥 They’ve made DeepSeek V4.1 Flash much more practical to run on Blackwell by squeezing the 552B MoE model into NVFP4. The result? lower inference costs without giving up the model’s core capabilities. You still get a 1M context window and native visual understanding, while retaining 98% agreement on agentic dialogue. That makes this a super strong fit for local agentic workflows. Grab the weights on huggingface 🤗 (link in 🧵↓)
원본 게시물 보기
아직 댓글이 없습니다. 첫 댓글을 남겨보세요!