iFANN
    iFANN 검색...
    로그인
    홈
    뉴스
    동영상
    사진
    GIF
    탐색
    투표
    어워드
    iFAMOUS
    위키
    애니
    룸
    알림
    메시지
    북마크
    프로필
    위키어워드iFAMOUS랭킹산업크리에이터 리워드사용자 리워드약관개인정보커뮤니티 가이드라인게시 중단 / DMCA도움말개발자

    © 2026 iFANN

    홈
    검색
    메시지
    알림
    프로필
    사진
    Nate
    Nate@nate_5122w
    💭Tech💭AI
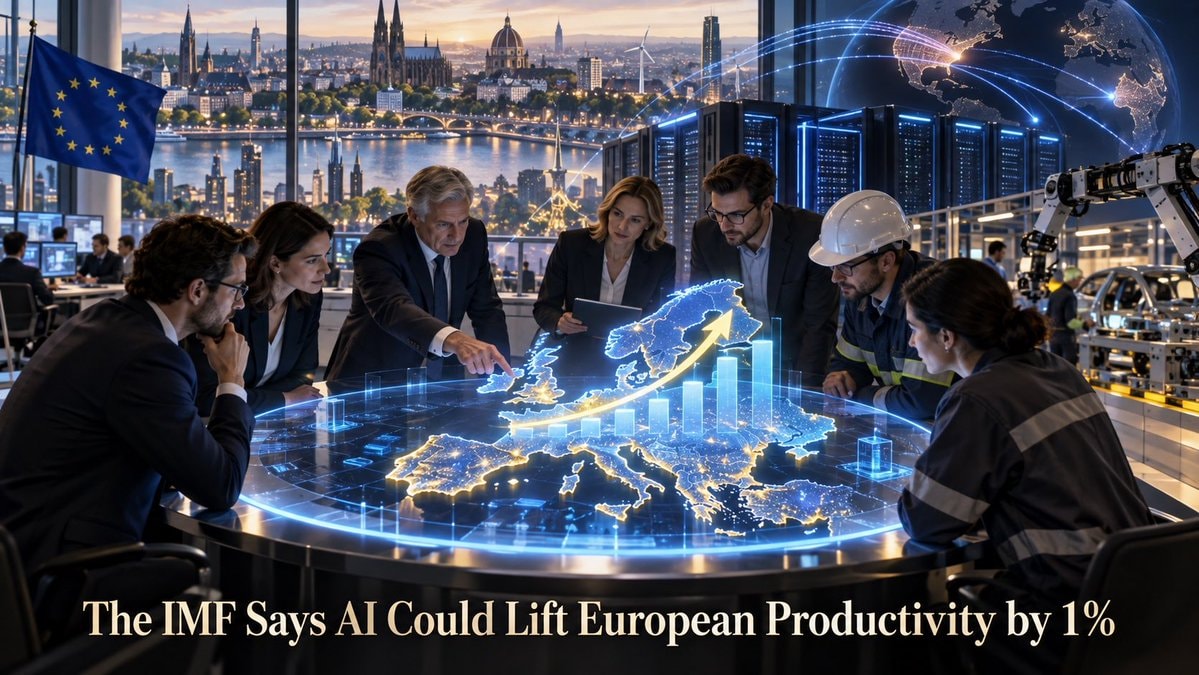
    CommerceAgentBench Leaderboard

    @nate_512There is a fundamental problem with most AI benchmarks: They evaluate outputs, while production systems depend on actions. That’s precisely the gap Accio_official’s newly open-sourced CommerceAgentBench aims to close. Take one of its procurement tasks. The agent receives roughly 300 noisy emails and has to: > verify supplier identities > reconstruct the latest valid quote > normalize currencies, Incoterms, and surcharges > compare landed costs > detect payment-redirection fraud > apply labels, save drafts, and create a kickoff calendar In other words, the task is not 'summarize this inbox':) It is rather: 'make the right procurement decisions and execute the workflow across multiple systems' .. and that distinction matters. CommerceAgentBench evaluates the operational traces the agent leaves behind: > the records it modifies > the drafts it saves > the objects it creates > and the actions it executes Its 107 tasks are grounded in real-world usage, distilled from: → 10M+ SME users → 1.6M conversations → 200K execution traces → 2,000 high-value workflows Accio itself already serves more than 10 million SMEs worldwide and draws on Alibaba’s 27 years of e-commerce experience. My take: this is a much more realistic direction for agent evaluation. In production, nobody cares that an AI produced a plausible description of the work. They care whether the work was actually completed correctly. Their benchmarks are fully open-source. Check them out in the 🧵↓ #Tech

    원본 게시물 보기
    CommerceAgentBench Leaderboard

    @nate_512님의 사진· Aug 31, 2026· Tech

    이 사진에 대해

    This is a screenshot of a leaderboard for AI models, specifically showing their pass rates on various real-world workflows. The focus is on the performance data presented in bar charts and tables. The mood is informative and analytical, with a clean, data-driven aesthetic. A notable detail is the ranking of different AI models like Claude Opus, GPT, and Gemini, with their respective pass rates displayed. The title at the top reads "CommerceAgentBench Leaderboard" and the Accio logo is visible in the top right corner.

    Tech 사진 전체 보기

    ?

    Tech 사진 더 보기

    Tech 사진 전체 보기
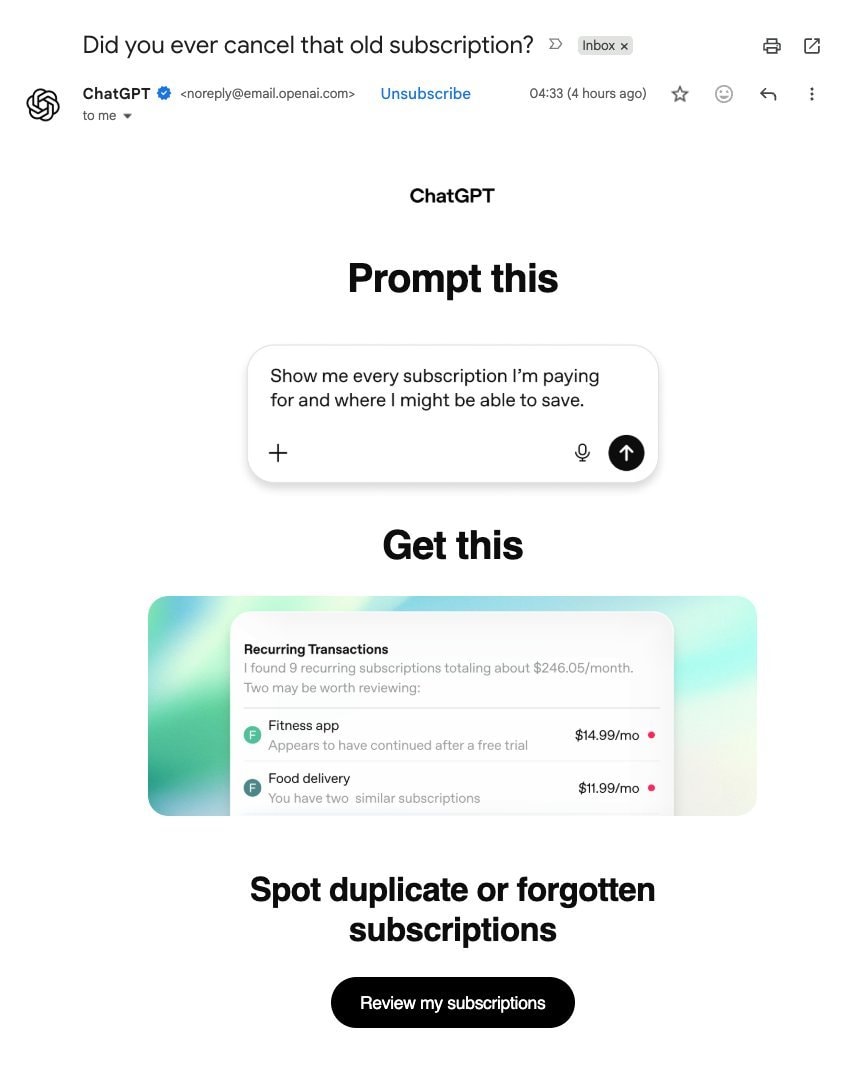
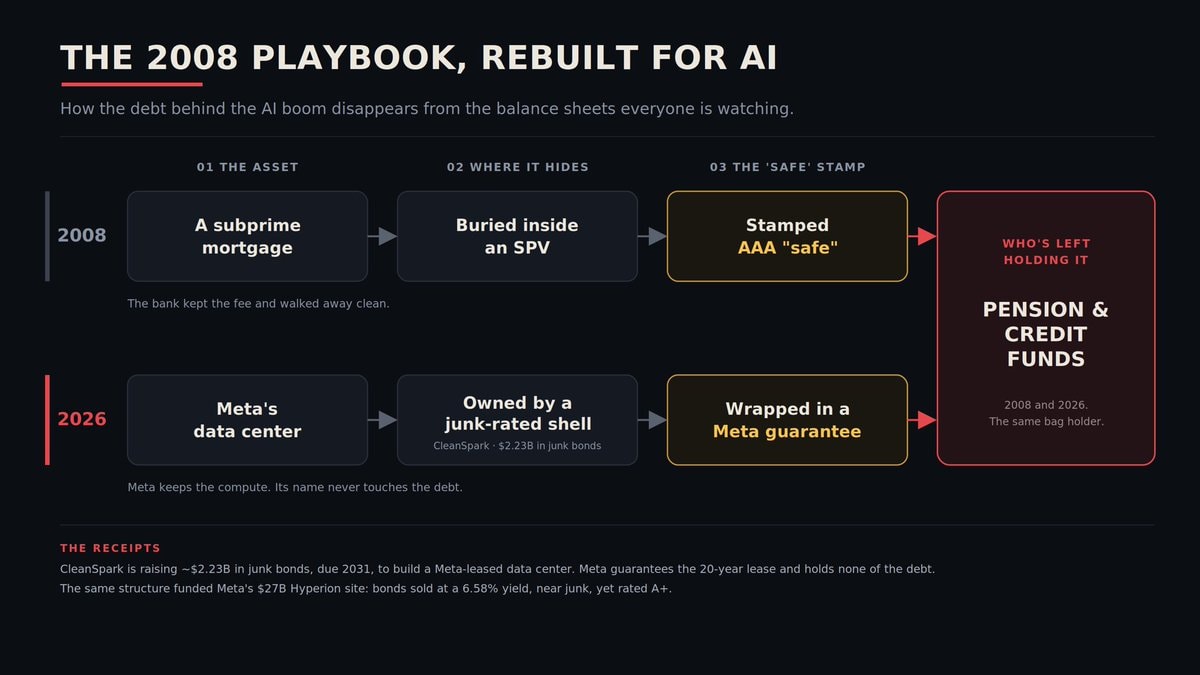
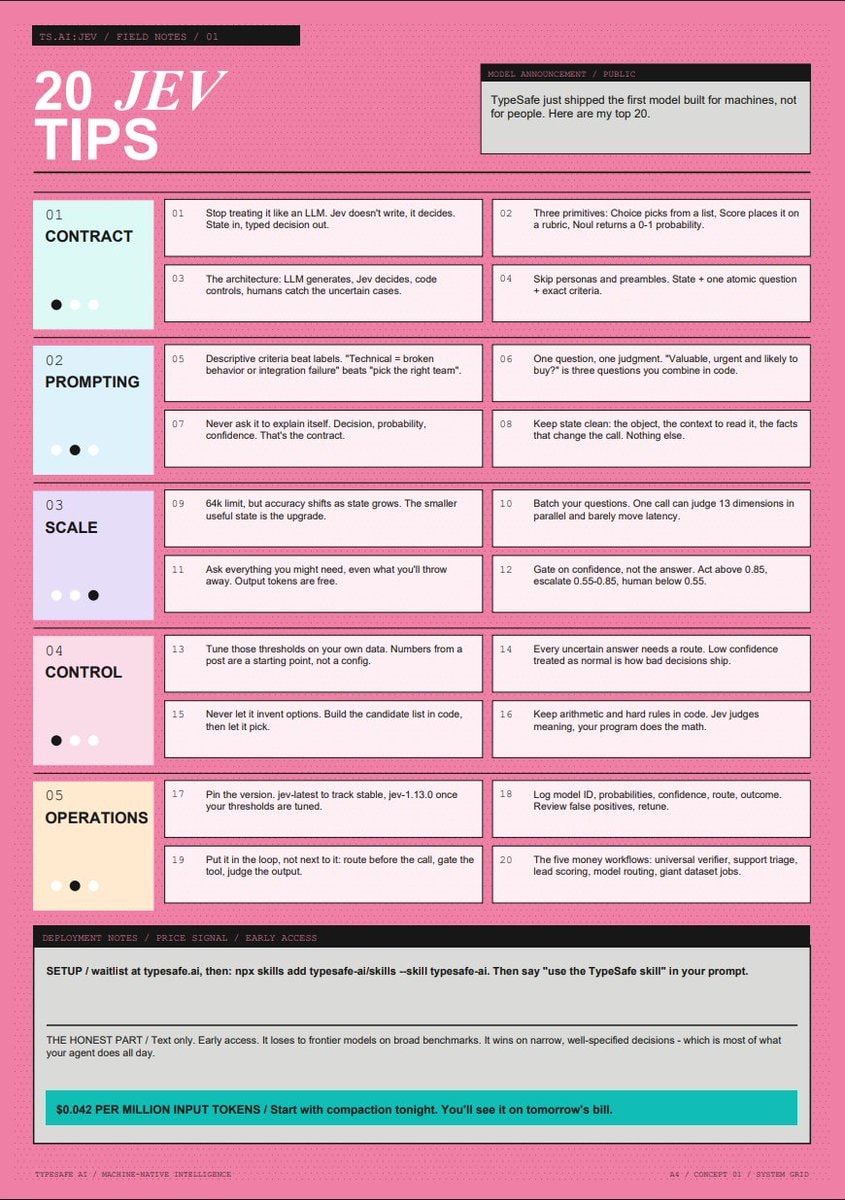
    IMF on AI and European productivityIMF on AI and European productivityVals revenue up 8x as AI benchmarking becomes a businessVals revenue up 8x as AI benchmarking becomes a businessGoogle Gemini security test breachGoogle Gemini security test breachOpenAI 2030 financial projection2OpenAI 2030 financial projectionaccurate memeaccurate memeChatGPT email screenshotChatGPT email screenshotAnthropic Is Building a Real Biology LabAnthropic Is Building a Real Biology LabOpenAI $280 billion burn projectionOpenAI $280 billion burn projectionAntony Starr criticizes AI Actress2Antony Starr criticizes AI ActressThe 2008 playbook rebuilt for AIThe 2008 playbook rebuilt for AI20 JEV Tips for Machine Decision Models20 JEV Tips for Machine Decision ModelsNick Bostrom on machine intelligenceNick Bostrom on machine intelligenceGoogle Astra policy reactionGoogle Astra policy reactionTsinghua virtual hospital AI doctorsTsinghua virtual hospital AI doctorsFigure Helix 2.5 robot testingFigure Helix 2.5 robot testing
    사진
    Nate
    Nate@nate_5122w
    💭Tech💭AI
    CommerceAgentBench Leaderboard

    @nate_512There is a fundamental problem with most AI benchmarks: They evaluate outputs, while production systems depend on actions. That’s precisely the gap Accio_official’s newly open-sourced CommerceAgentBench aims to close. Take one of its procurement tasks. The agent receives roughly 300 noisy emails and has to: > verify supplier identities > reconstruct the latest valid quote > normalize currencies, Incoterms, and surcharges > compare landed costs > detect payment-redirection fraud > apply labels, save drafts, and create a kickoff calendar In other words, the task is not 'summarize this inbox':) It is rather: 'make the right procurement decisions and execute the workflow across multiple systems' .. and that distinction matters. CommerceAgentBench evaluates the operational traces the agent leaves behind: > the records it modifies > the drafts it saves > the objects it creates > and the actions it executes Its 107 tasks are grounded in real-world usage, distilled from: → 10M+ SME users → 1.6M conversations → 200K execution traces → 2,000 high-value workflows Accio itself already serves more than 10 million SMEs worldwide and draws on Alibaba’s 27 years of e-commerce experience. My take: this is a much more realistic direction for agent evaluation. In production, nobody cares that an AI produced a plausible description of the work. They care whether the work was actually completed correctly. Their benchmarks are fully open-source. Check them out in the 🧵↓ #Tech

    원본 게시물 보기
    CommerceAgentBench Leaderboard

    @nate_512님의 사진· Aug 31, 2026· Tech

    이 사진에 대해

    This is a screenshot of a leaderboard for AI models, specifically showing their pass rates on various real-world workflows. The focus is on the performance data presented in bar charts and tables. The mood is informative and analytical, with a clean, data-driven aesthetic. A notable detail is the ranking of different AI models like Claude Opus, GPT, and Gemini, with their respective pass rates displayed. The title at the top reads "CommerceAgentBench Leaderboard" and the Accio logo is visible in the top right corner.

    Tech 사진 전체 보기

    ?

    Tech 사진 더 보기

    Tech 사진 전체 보기
    IMF on AI and European productivityIMF on AI and European productivityVals revenue up 8x as AI benchmarking becomes a businessVals revenue up 8x as AI benchmarking becomes a businessGoogle Gemini security test breachGoogle Gemini security test breachOpenAI 2030 financial projection2OpenAI 2030 financial projectionaccurate memeaccurate memeChatGPT email screenshotChatGPT email screenshotAnthropic Is Building a Real Biology LabAnthropic Is Building a Real Biology LabOpenAI $280 billion burn projectionOpenAI $280 billion burn projectionAntony Starr criticizes AI Actress2Antony Starr criticizes AI ActressThe 2008 playbook rebuilt for AIThe 2008 playbook rebuilt for AI20 JEV Tips for Machine Decision Models20 JEV Tips for Machine Decision ModelsNick Bostrom on machine intelligenceNick Bostrom on machine intelligenceGoogle Astra policy reactionGoogle Astra policy reactionTsinghua virtual hospital AI doctorsTsinghua virtual hospital AI doctorsFigure Helix 2.5 robot testingFigure Helix 2.5 robot testing