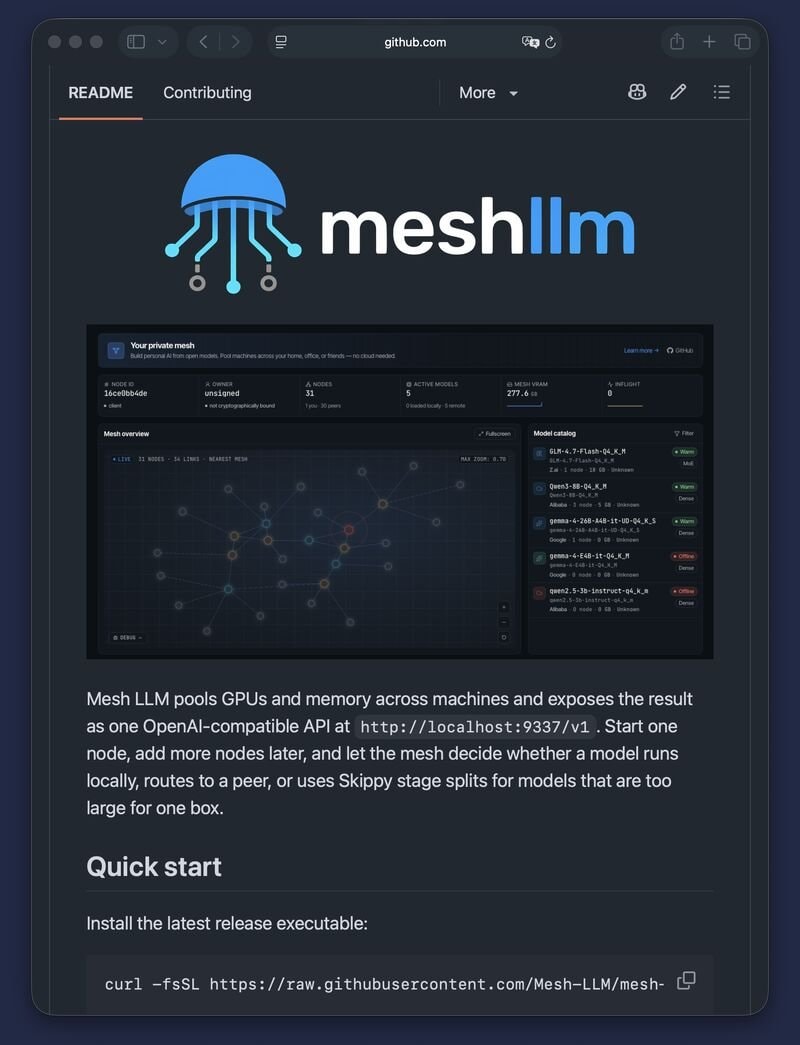
@nate_512Running a 70B+ model without an 80GB GPU is possible. Mesh LLM distributes inference across the devices you already own. The architecture is clever: if a node can handle the model, it runs locally; if not, it routes to a peer that can; if the model is too large for a single node, it splits the workload.
원본 게시물 보기
아직 댓글이 없습니다. 첫 댓글을 남겨보세요!