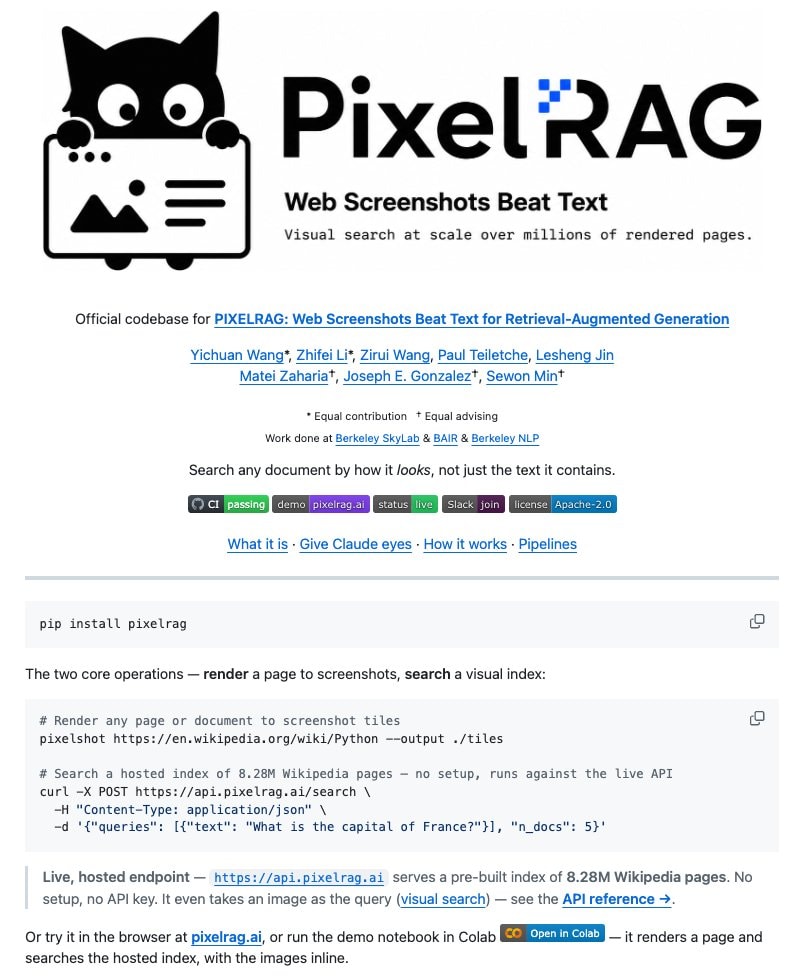
@nate_512A new approach to web scraping for RAG systems: researchers at UC Berkeley have open-sourced PixelRAG, a tool that bypasses HTML parsing entirely. Instead of extracting text from a page and embedding chunks, it captures full-page screenshots and uses visual search over millions of rendered pages. The GitHub repository lists authors Yichuan Wang, Zhifei Li, Zirui Wang, Paul Teleltche, Lesheng Jin, Matei Zaharia, Joseph E. Gonzalez, and Sewon Min. The tool can be installed via pip and includes code for rendering pages to
원본 게시물 보기
아직 댓글이 없습니다. 첫 댓글을 남겨보세요!